Security, Trust, Identity & Quantum Risk
The Failure to Classify: How Context-Blind Safety Rails Break Trust
AI safety systems that cannot distinguish symbolic expression from literal harm fail at the classification layer.
Chris Ciappa· January 26, 2026· 5 min read
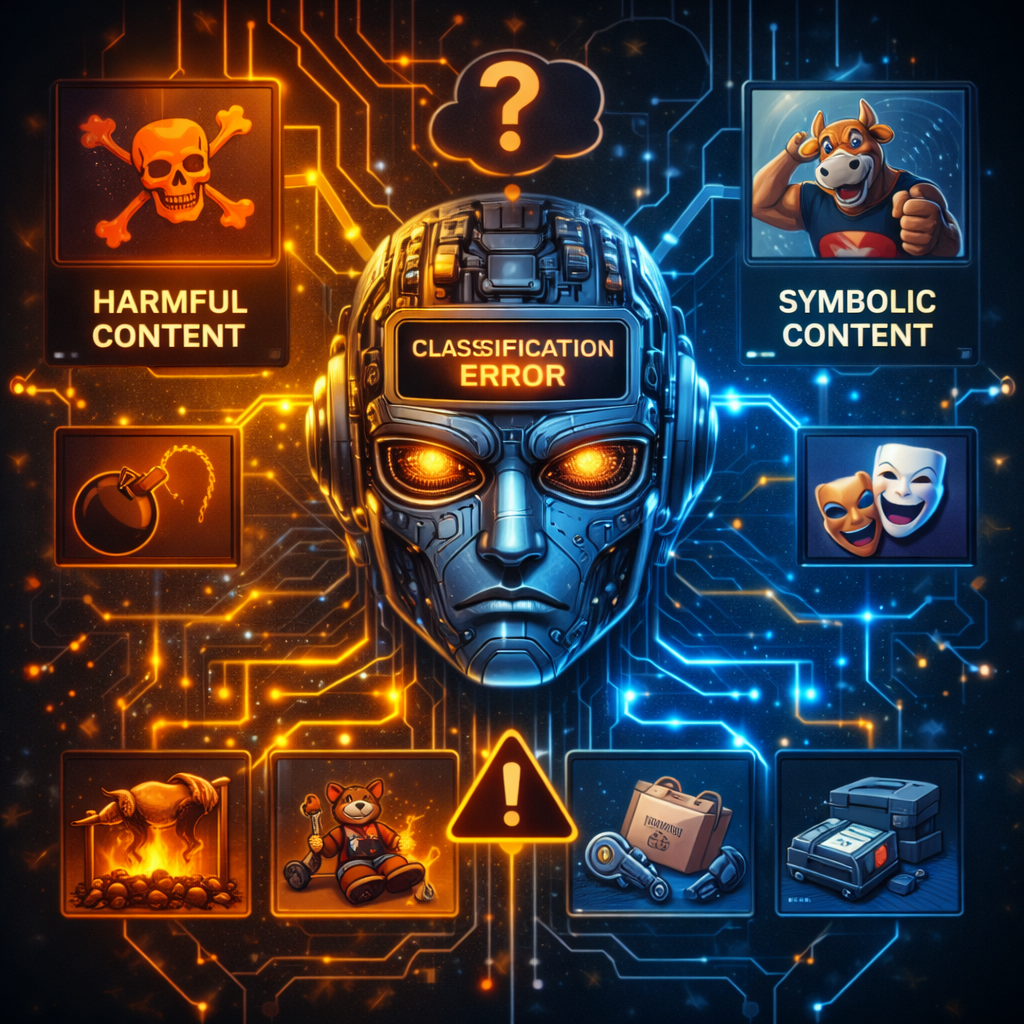
AI safety systems that cannot distinguish symbolic expression from literal harm fail at the classification layer.
Member article
Full article access requires Synth Membership
This article is available to Synth members. Membership is $50 per year and unlocks member articles through your Samirac account.